Models
An automated system checks the model lists on this page against live Hyperstack data every day. When the live data changes, the documentation team updates the page. Learn how these docs stay accurate.
The models available for inference in AI Studio, by modality, with pricing and where to find them.
Hyperstack AI Studio provides a catalog of text and image models that you can use for inference through the playgrounds and the API. This page lists the available models by modality, explains how they are priced, and shows where to find them in AI Studio.
Models are served through third-party provider API integrations and are listed with their prices on the Inference page in AI Studio. Because these models are provided by external services, AI Studio cannot guarantee continued availability, and access may be revoked at any time if a provider changes or removes support for a model. Pricing is also subject to change and may be updated by the provider at any time. Requests may be processed by external providers in order to fulfill your request, and usage is subject to the availability, reliability, and data-handling practices of those providers.
Model Modalities
Hyperstack AI Studio offers a range of models spanning multiple modalities:
- Text-to-Text – Generate text from text inputs (e.g., chat, summarization, code generation)
- Image-to-Text – Generate text from an image and a text prompt (e.g., describe or answer questions about an image)
- Text-to-Image – Generate images from text prompts
- Image-to-Image – Transform or edit existing images using image inputs
Learn more about each model type, including supported models and how to use them in AI Studio:
Text-to-Text Models
Text-to-text models process text inputs and generate text outputs. These are used for tasks such as chat, summarization, reasoning, and code generation. These models can be used within the Text Playground.
Click to expand list of text-to-text models
The models available can change at any time. For the list of models currently available, see the Models tab in AI Studio.
- alpindale/WizardLM-2-8x22B
- arcee-ai/Trinity-Mini
- baichuan-inc/Baichuan-M2-32B
- baidu/ERNIE-4.5-21B-A3B-PT
- baidu/ERNIE-4.5-300B-A47B-Base-PT
- deepcogito/cogito-671b-v2.1
- deepcogito/cogito-671b-v2.1-FP8
- deepcogito/cogito-v2-preview-llama-405B
- deepcogito/cogito-v2-preview-llama-70B
- deepreinforce-ai/Ornith-1.0-35B
- deepreinforce-ai/Ornith-1.0-35B-FP8
- deepseek-ai/DeepSeek-Prover-V2-671B
- deepseek-ai/DeepSeek-R1
- deepseek-ai/DeepSeek-R1-0528
- deepseek-ai/DeepSeek-R1-0528-Qwen3-8B
- deepseek-ai/DeepSeek-R1-Distill-Llama-70B
- deepseek-ai/DeepSeek-R1-Distill-Llama-8B
- deepseek-ai/DeepSeek-R1-Distill-Qwen-1.5B
- deepseek-ai/DeepSeek-R1-Distill-Qwen-14B
- deepseek-ai/DeepSeek-R1-Distill-Qwen-32B
- deepseek-ai/DeepSeek-R1-Distill-Qwen-7B
- deepseek-ai/DeepSeek-V3
- deepseek-ai/DeepSeek-V3-0324
- deepseek-ai/DeepSeek-V3.1
- deepseek-ai/DeepSeek-V3.1-Terminus
- deepseek-ai/DeepSeek-V3.2
- deepseek-ai/DeepSeek-V3.2-Exp
- deepseek-ai/DeepSeek-V4-Flash
- deepseek-ai/DeepSeek-V4-Flash-0731
- deepseek-ai/DeepSeek-V4-Pro
- deepseek-ai/DeepSeek-V4-Pro-0813
- EssentialAI/rnj-1-instruct
- google/gemma-2-2b-it
- google/gemma-2-9b-it
- google/gemma-3-12b-it
- google/gemma-3-27b-it
- google/gemma-3-4b-it
- google/gemma-3n-E4B-it
- google/gemma-4-26B-A4B-it
- google/gemma-4-31B-it
- ibm-granite/granite-4.2-30b
- ibm-granite/granite-4.2-3b
- ibm-granite/granite-4.2-8b
- inclusionAI/Ling-2.6-1T
- inclusionAI/Ling-3.0-flash
- marin-community/marin-8b-instruct
- meta-llama/Llama-3.2-3B-Instruct
- meta-llama/Llama-4-Maverick-17B-128E-Instruct-FP8
- meta-llama/Llama-4-Scout-17B-16E-Instruct
- meta-llama/Meta-Llama-3-70B-Instruct
- meta-llama/Meta-Llama-3-8B-Instruct
- meta-models/Muse-Glimmer-30B
- microsoft/phi-4
- MiniMaxAI/MiniMax-M1-80k
- MiniMaxAI/MiniMax-M2
- MiniMaxAI/MiniMax-M2.1
- MiniMaxAI/MiniMax-M2.5
- MiniMaxAI/MiniMax-M2.7
- MiniMaxAI/MiniMax-M3
- moonshotai/Kimi-K2-Instruct
- moonshotai/Kimi-K2-Instruct-0905
- moonshotai/Kimi-K2-Thinking
- moonshotai/Kimi-K2.5
- moonshotai/Kimi-K2.6
- moonshotai/Kimi-K2.7-Code
- moonshotai/Kimi-K3
- NousResearch/Hermes-2-Pro-Llama-3-8B
- NousResearch/Hermes-3-Llama-3.1-70B
- NousResearch/Hermes-4-405B
- NousResearch/Hermes-4-70B
- nvidia/Llama-3_1-Nemotron-Ultra-253B-v1
- nvidia/NVIDIA-Nemotron-3-Nano-30B-A3B-FP8
- nvidia/NVIDIA-Nemotron-3-Ultra-550B-A55B-BF16
- nvidia/NVIDIA-Nemotron-3-Ultra-550B-A55B-NVFP4
- nvidia/NVIDIA-Nemotron-Nano-12B-v2
- openai/gpt-oss-20b
- pearl-ai/Gemma-4-31B-it-pearl
- PrimeIntellect/INTELLECT-3-FP8
- Qwen/Qwen2.5-72B-Instruct
- Qwen/Qwen2.5-7B-Instruct
- Qwen/Qwen2.5-Coder-32B-Instruct
- Qwen/Qwen2.5-Coder-3B-Instruct
- Qwen/Qwen2.5-Coder-7B
- Qwen/Qwen2.5-Coder-7B-Instruct
- Qwen/Qwen2.5-VL-72B-Instruct
- Qwen/Qwen3-14B
- Qwen/Qwen3-235B-A22B
- Qwen/Qwen3-235B-A22B-FP8
- Qwen/Qwen3-235B-A22B-Instruct-2507
- Qwen/Qwen3-235B-A22B-Thinking-2507
- Qwen/Qwen3-30B-A3B
- Qwen/Qwen3-30B-A3B-Instruct-2507
- Qwen/Qwen3-30B-A3B-Thinking-2507
- Qwen/Qwen3-32B
- Qwen/Qwen3-4B-Instruct-2507
- Qwen/Qwen3-4B-Thinking-2507
- Qwen/Qwen3-8B
- Qwen/Qwen3-Coder-30B-A3B-Instruct
- Qwen/Qwen3-Coder-480B-A35B-Instruct
- Qwen/Qwen3-Coder-480B-A35B-Instruct-FP8
- Qwen/Qwen3-Coder-Next
- Qwen/Qwen3-Coder-Next-FP8
- Qwen/Qwen3-Next-80B-A3B-Instruct
- Qwen/Qwen3-Next-80B-A3B-Thinking
- Qwen/Qwen3-VL-235B-A22B-Instruct
- Qwen/Qwen3-VL-235B-A22B-Thinking
- Qwen/Qwen3-VL-30B-A3B-Instruct
- Qwen/Qwen3.5-122B-A10B
- Qwen/Qwen3.5-27B
- Qwen/Qwen3.5-35B-A3B
- Qwen/Qwen3.5-397B-A17B
- Qwen/Qwen3.5-9B
- Qwen/Qwen3.6-27B
- Qwen/Qwen3.6-35B-A3B
- Qwen/Qwen3.8-2.4T-A95B
- Qwen/Qwen3.8-27B
- Qwen/QwQ-32B
- Sao10K/L3-70B-Euryale-v2.1
- Sao10K/L3-8B-Lunaris-v1
- Sao10K/L3-8B-Stheno-v3.2
- stepfun-ai/Step-3.5-Flash
- stepfun-ai/Step-3.7-Flash
- tencent/Hy3
- thinkingmachines/Inkling
- tokyotech-llm/Llama-3.3-Swallow-70B-Instruct-v0.4
- XiaomiMiMo/MiMo-V2-Flash
- XiaomiMiMo/MiMo-V2.5
- XiaomiMiMo/MiMo-V2.5-Pro
- zai-org/AutoGLM-Phone-9B-Multilingual
- zai-org/GLM-4-32B-0414
- zai-org/GLM-4.5
- zai-org/GLM-4.5-Air
- zai-org/GLM-4.5-Air-FP8
- zai-org/GLM-4.5V
- zai-org/GLM-4.6
- zai-org/GLM-4.6V-Flash
- zai-org/GLM-4.7
- zai-org/GLM-4.7-Flash
- zai-org/GLM-4.7-FP8
- zai-org/GLM-5
- zai-org/GLM-5.1
- zai-org/GLM-5.1-FP8
- zai-org/GLM-5.2
- zai-org/GLM-5.3-Flash
Image-to-Text Models
Image-to-text models (also called vision-language models) accept an image alongside your text prompt and generate a text response, such as describing an image or answering questions about it. These models can be used within the Text Playground by attaching an image to your message.
Click to expand list of image-to-text models
The models available can change at any time. For the list of models currently available, see the Models tab in AI Studio.
- google/gemma-3-12b-it
- google/gemma-3-27b-it
- google/gemma-3-4b-it
- google/gemma-3n-E4B-it
- google/gemma-4-26B-A4B-it
- google/gemma-4-31B-it
- meta-llama/Llama-4-Maverick-17B-128E-Instruct-FP8
- meta-llama/Llama-4-Scout-17B-16E-Instruct
- meta-models/Muse-Glimmer-30B
- MiniMaxAI/MiniMax-M3
- moonshotai/Kimi-K2.5
- moonshotai/Kimi-K2.6
- moonshotai/Kimi-K2.7-Code
- moonshotai/Kimi-K3
- Qwen/Qwen2.5-VL-72B-Instruct
- Qwen/Qwen3-VL-235B-A22B-Instruct
- Qwen/Qwen3-VL-235B-A22B-Thinking
- Qwen/Qwen3-VL-30B-A3B-Instruct
- Qwen/Qwen3.5-122B-A10B
- Qwen/Qwen3.5-27B
- Qwen/Qwen3.5-35B-A3B
- Qwen/Qwen3.5-397B-A17B
- Qwen/Qwen3.5-9B
- Qwen/Qwen3.6-27B
- Qwen/Qwen3.6-35B-A3B
- Qwen/Qwen3.8-27B
- stepfun-ai/Step-3.7-Flash
- thinkingmachines/Inkling
- zai-org/AutoGLM-Phone-9B-Multilingual
- zai-org/GLM-4.5V
- zai-org/GLM-4.6V-Flash
Text-to-Image Models
Text-to-image models (vision models) generate images from text prompts. These are used for creating visuals such as illustrations, product mockups, and creative assets. These models can be used within the Image Playground.
For the most up-to-date availability and pricing, see the Vision Models tab.
Click to expand list of text-to-image models
The models available can change at any time. For the models currently available and up-to-date pricing, see Vision Models tab in AI Studio.
- CogView4-6B
- FLUX.1-dev
- FLUX.1-Krea-dev
- FLUX.1-schnell
- GLM-Image
- HiDream-I1-Fast
- HiDream-I1-Full
- HunyuanImage-3.0
- Hyper-SD
- LongCat-Image
- Qwen-Image
- Qwen-Image-2512
- SRPO
- stable-diffusion-3.5-large
- stable-diffusion-3.5-large-turbo
- stable-diffusion-3.5-medium
- Z-Image-Turbo
Image-to-Image Models
Image-to-image models (vision models) transform or edit existing images using an input image and optional prompts. These are used for workflows such as style transfer, image enhancement, and guided edits. These models can be used within the Image Playground.
For the most up-to-date availability and pricing, see the Vision Models tab.
Click to expand list of image-to-image models
The models available can change at any time. For the models currently available and up-to-date pricing, see Vision Models tab in AI Studio.
- FLUX.1-Kontext-dev
- FLUX.2-dev
- LongCat-Image-Edit
- Qwen-Image-Edit
- Qwen-Image-Edit-2511
Viewing Models
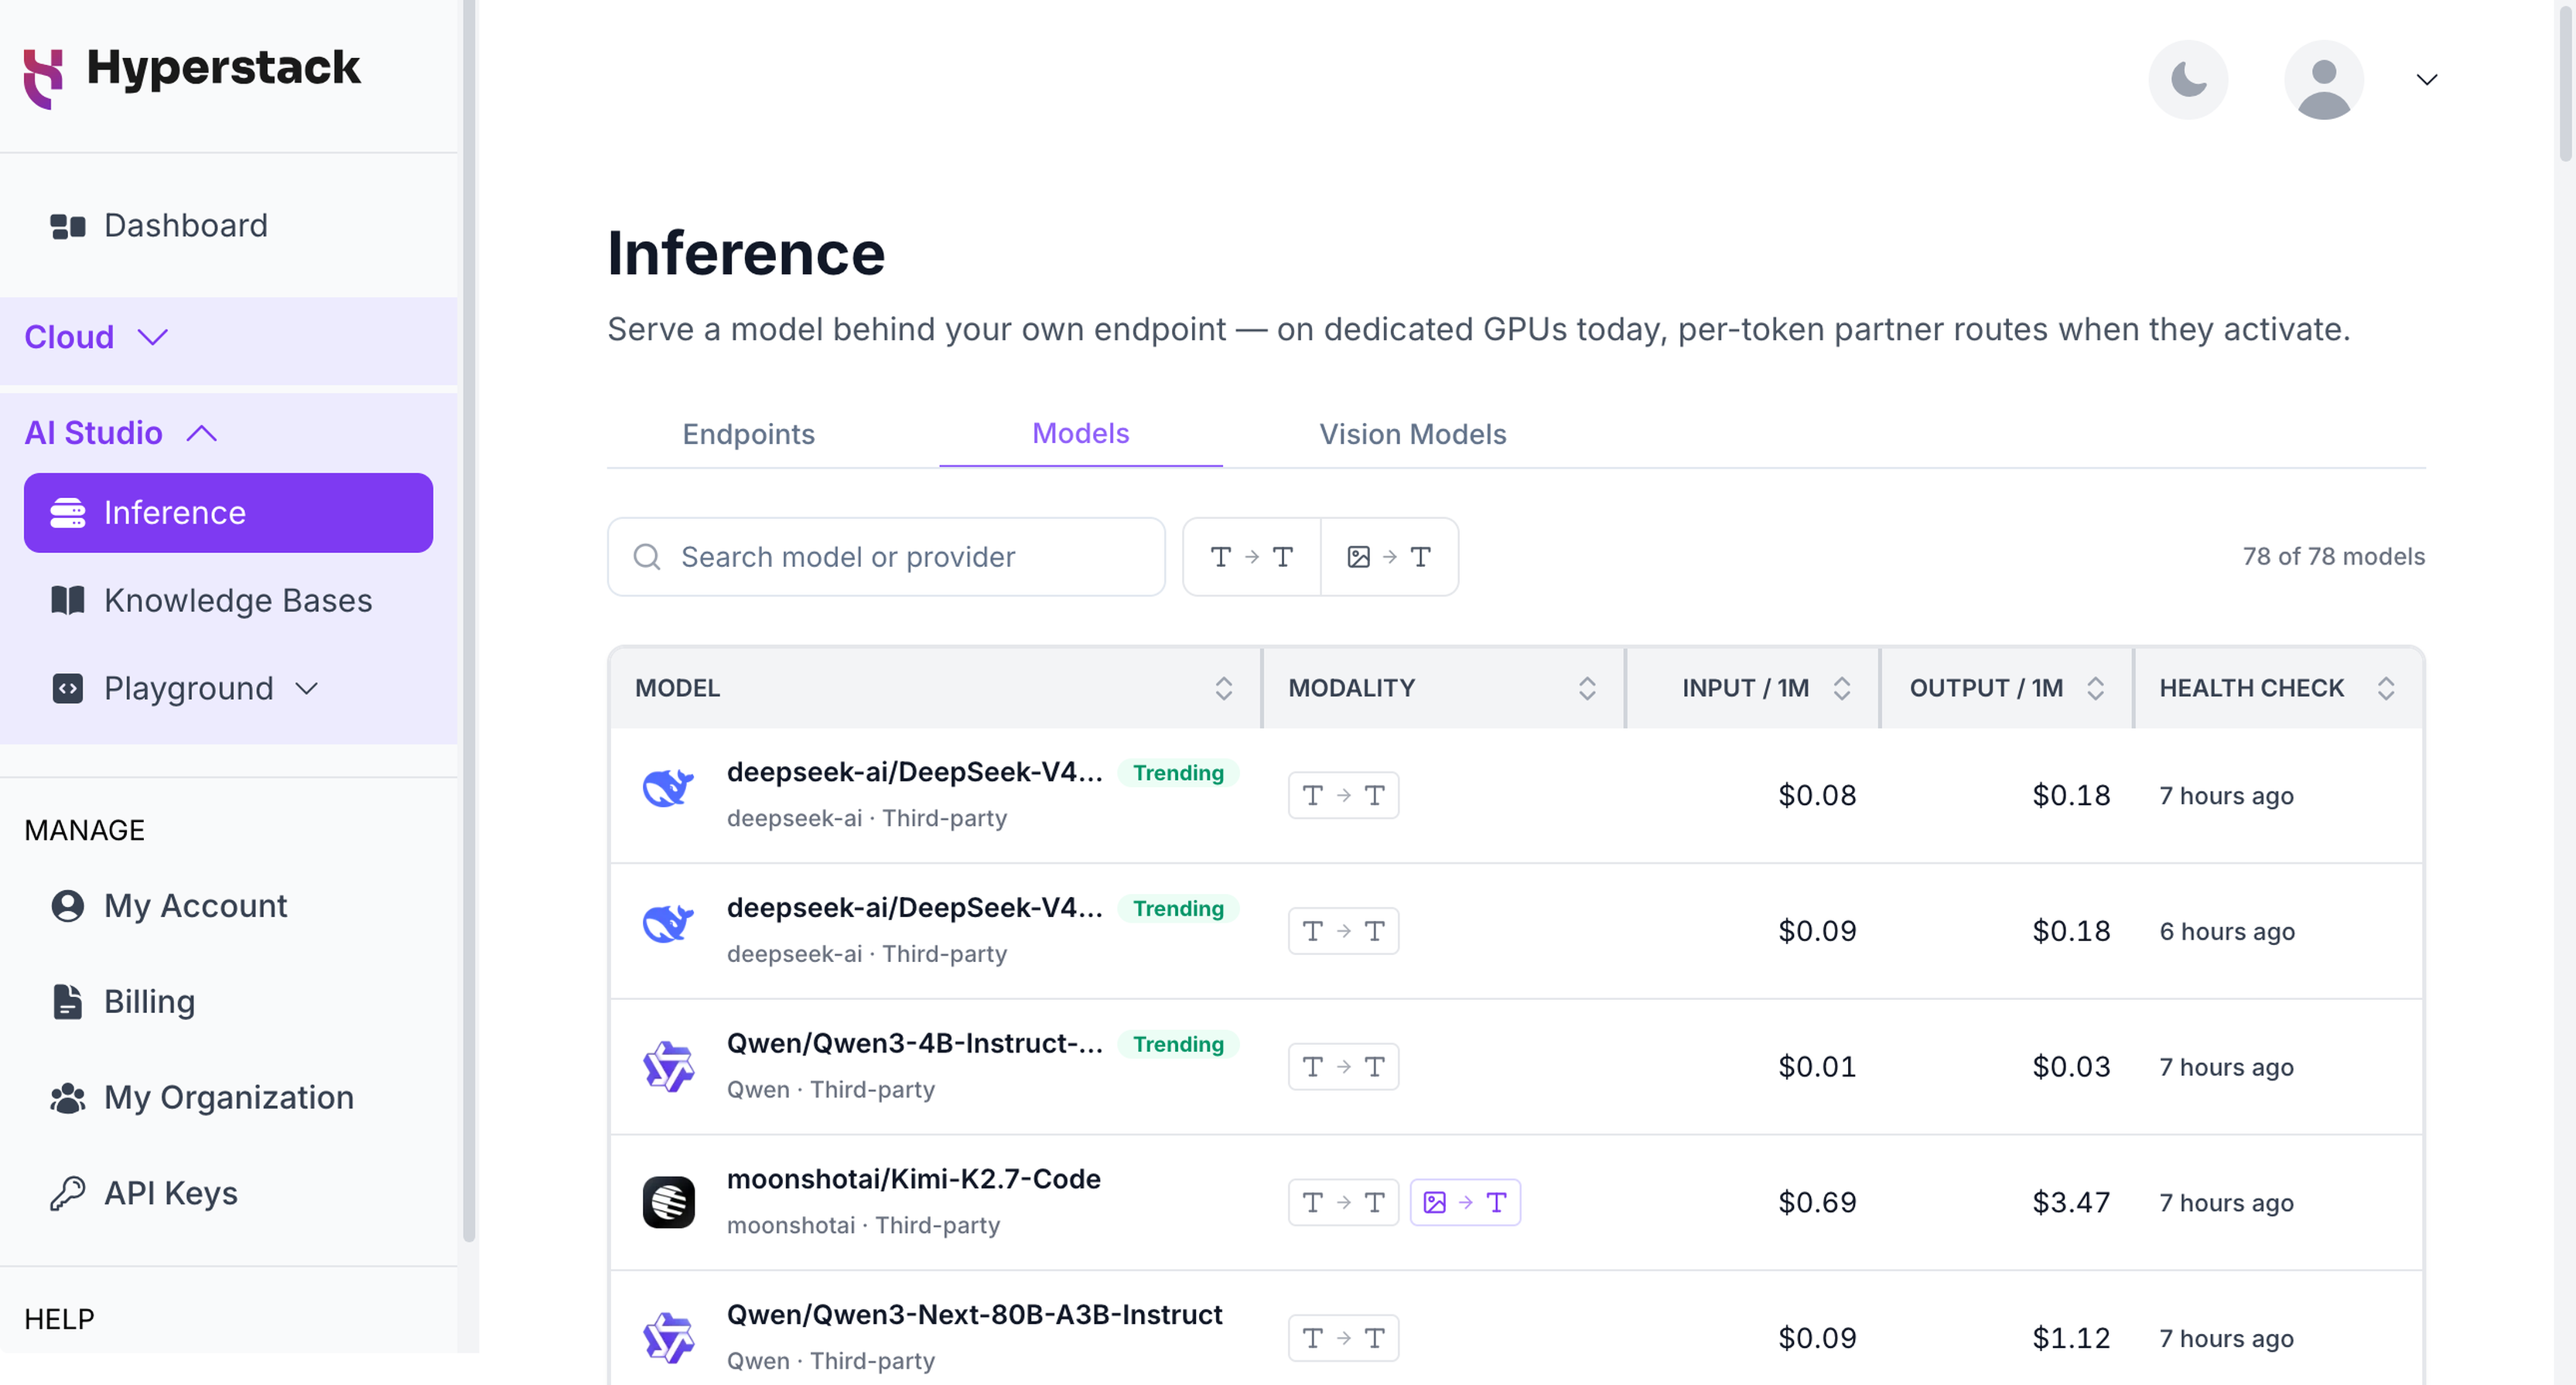
The Inference page in AI Studio lists every available model and its current price on two tabs:
- Models: text-to-text and image-to-text models, with the cost per 1 million input and output tokens.
- Vision Models: image generation models, with the cost per 16×16 patch.
Each row also shows the model's icon, its provider, its modality, and when it was last health-checked. Models are listed by popularity, most used first, and the most-used models carry a Trending badge. Search by model or provider name, or filter by modality, to narrow the list.
Select a model to open its details, including its availability, pricing, and modalities. To copy the model's ID, click Copy model ID.
Pricing
Models are billed through AI Studio and appear in its unified billing system.
Pricing depends on what the model generates, not on whether it processes images:
-
Text-to-Text and Image-to-Text Models generate text and are billed per token. Image-to-text models are vision-language models: they accept an image as input, which is included in your input tokens, and return a text response.
- Cost per 1 million input tokens
- Cost per 1 million output tokens
-
Text-to-Image and Image-to-Image Models generate images and are billed per patch.
- Cost per 16×16 patch, where 1 patch = 256 pixels (a 16×16 pixel region) of generated image output. See the Vision Models tab for the most up-to-date per-model pricing.
Pricing is subject to change. For the most up-to-date pricing, refer to the Models tab in AI Studio. For more details on billing within AI Studio, click here.